Match where it is rather than how it's spelled

Here are two addresses. Tell me if they're the same place.
123 Main Street, Suite 400, Springfield IL 62704
123 Main St #400, Springfield, Illinois
They are. Now compare these two:
Jyllandsgade 15, 9000 Aalborg
Jyllandsgade 75, 9000 Aalborg
They are different places, 650 meters apart.
A string-similarity matcher scores the first pair, the same place, low because of different punctuation, "Street" vs "St", and a reordered unit. It scores the second pair, different places, at 0.96 because they differ by one character. The usual tool gets both pairs wrong. A threshold change cannot fix this, because string similarity measures the wrong thing.
An address is a location wearing a costume
An address describes a point on the Earth. Its written form is lossy and inconsistent, and a hundred different intake forms format it differently. "650 meters apart" is a fact about the locations. "One character apart" is a fact about how they were written.
Here is the same matching decision, scored two ways:
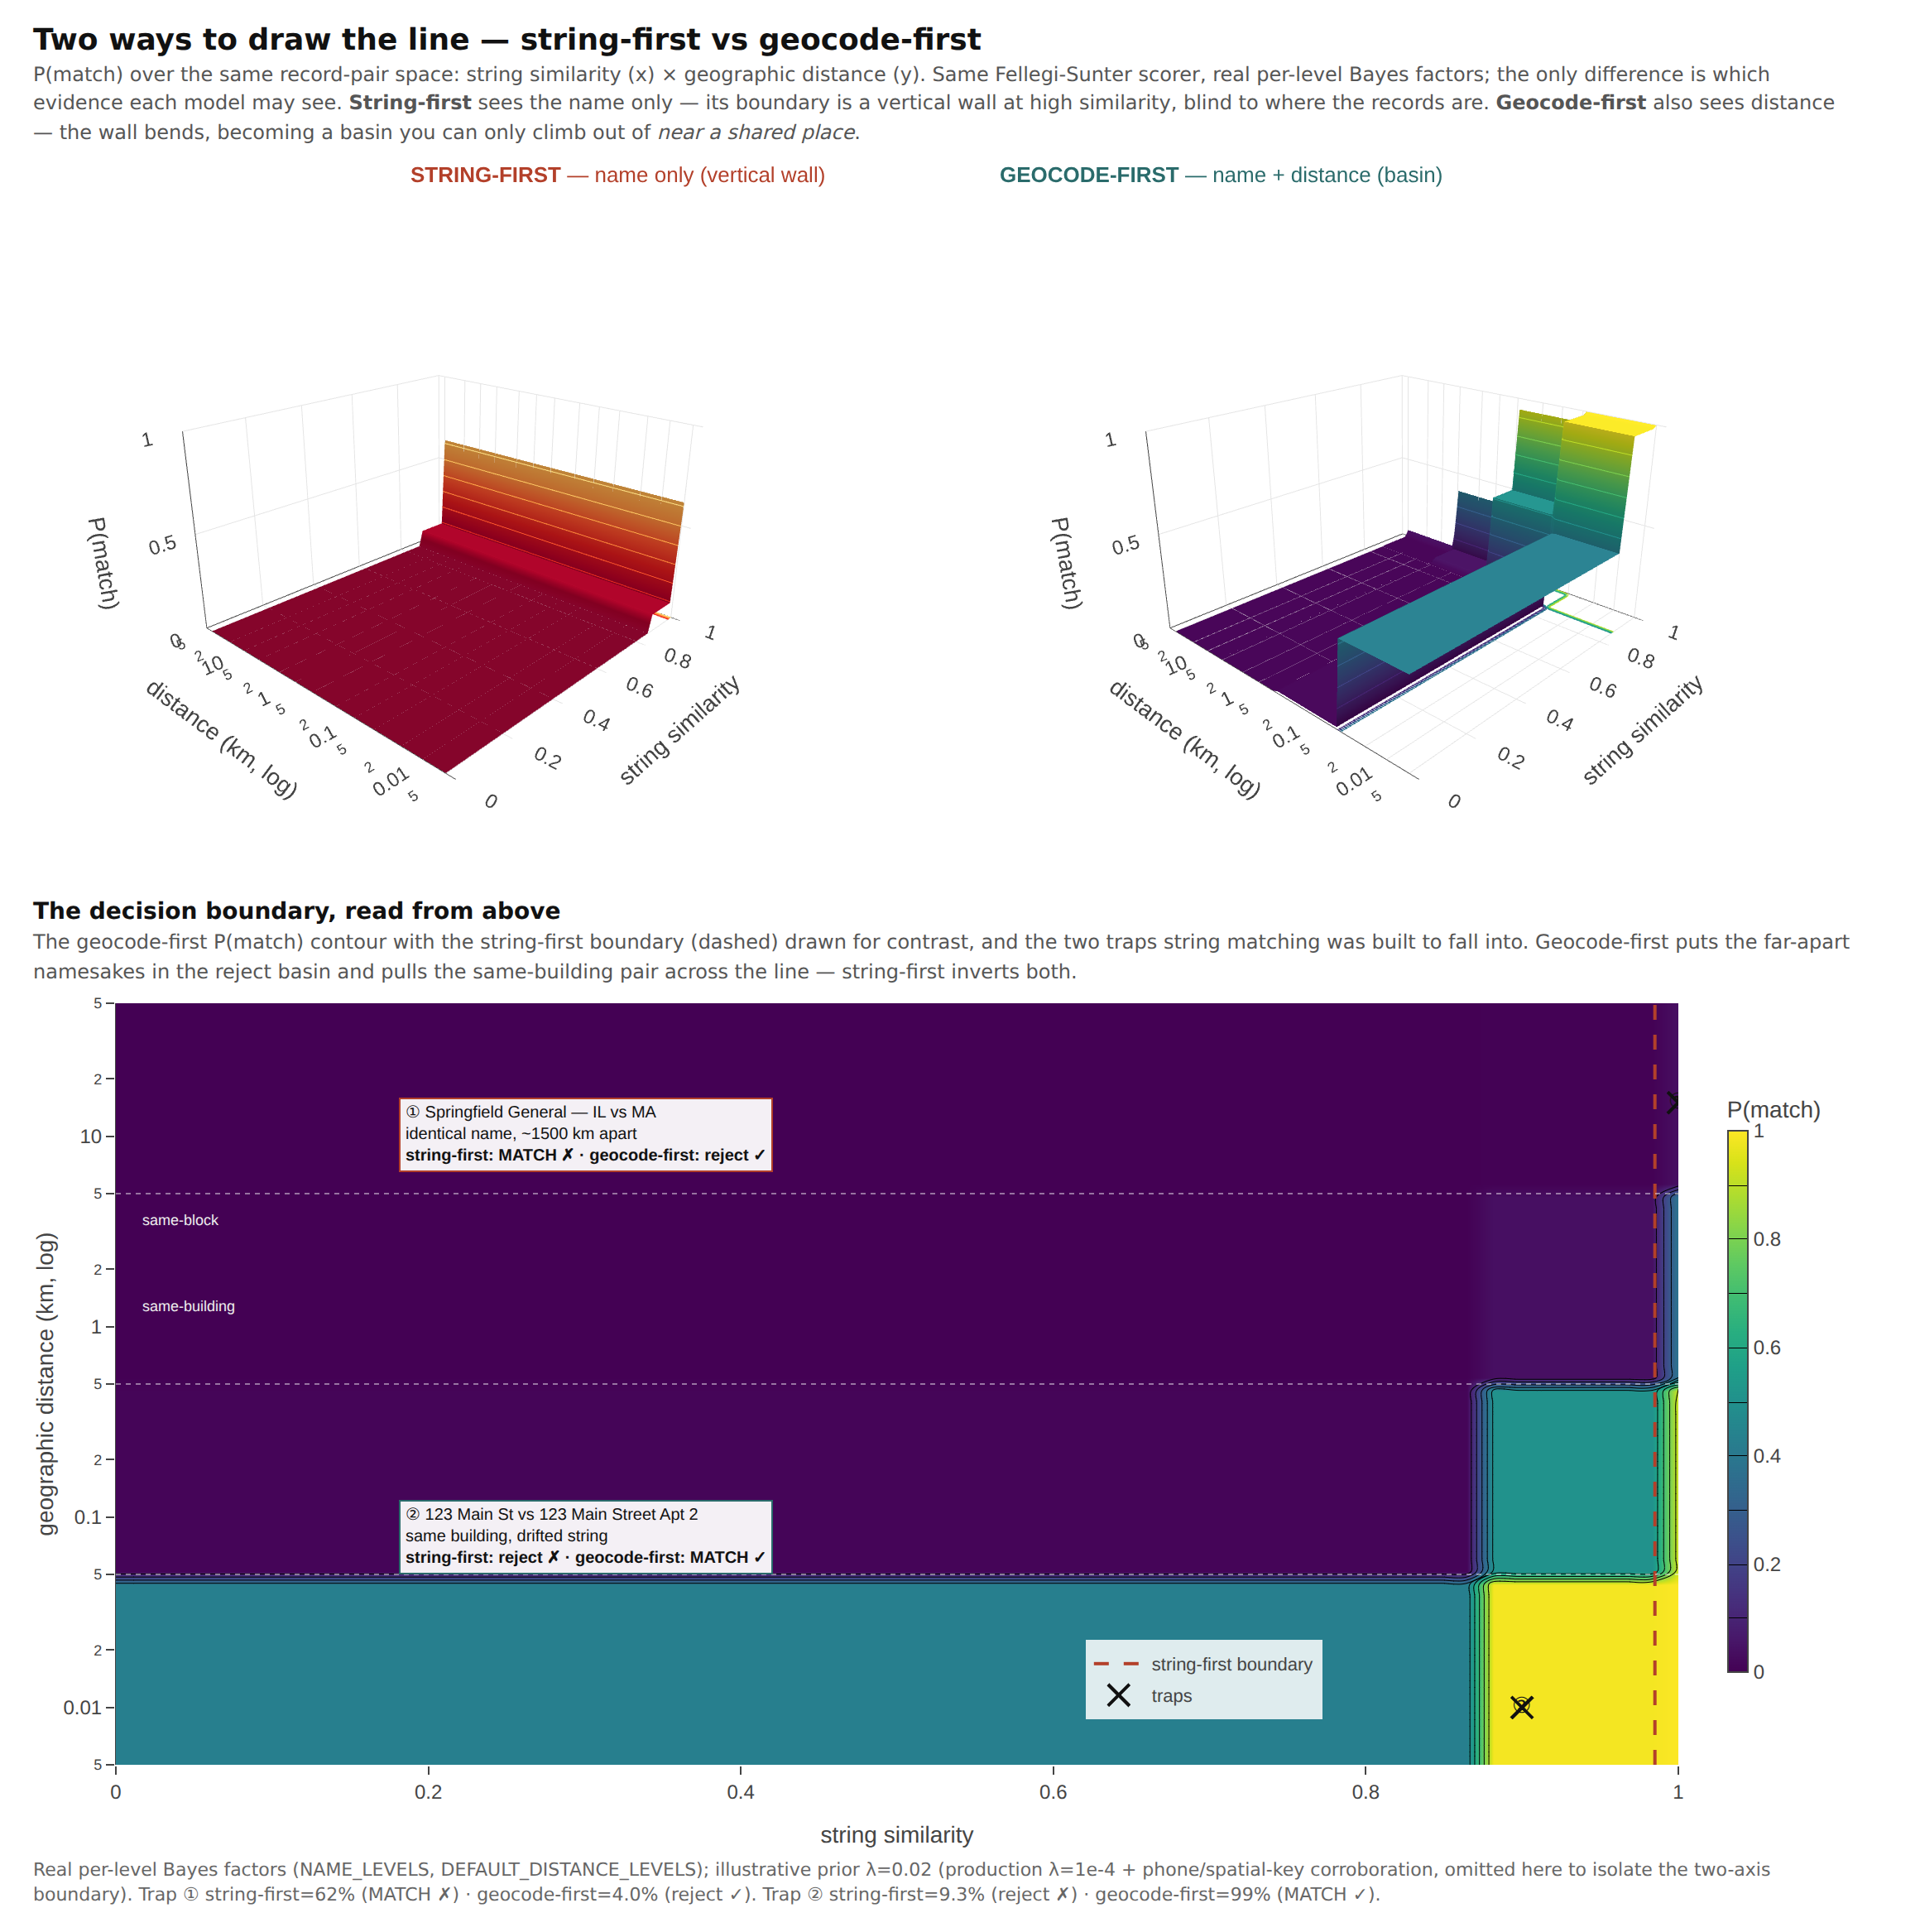
String-first draws its decision boundary vertically. Two records match if their spelling is close enough, regardless of where on Earth they sit. Geocode-first draws the boundary horizontally. Geographically close records are plausible matches, distant records are rejected, and spelling only breaks ties between close candidates. The two failure cases (the same place written differently, and different places written almost identically) sit in the corners where those boundaries disagree, and geocode-first handles both correctly. The image above shows the same Fellegi-Sunter scorer with real per-field weights, run twice: once with only the name, and once with distance as well. Geography gets more weight by design.
We therefore stopped matching on the written form. Mailwoman is a calibrated street-level geocoder. Given a messy address line, it returns a coordinate, a resolution tier, and a calibrated uncertainty. With those, entity resolution works differently. You match on the resolved place: the coordinate, the canonical key, and the admin hierarchy. The string is evidence about the place, and the place is the identity.
Three things change as a result.
Geocode-first blocking partitions records into cells. The expensive part of matching a million records is finding the candidate pairs to score without comparing all 500 billion of them, and scoring each pair is cheap by comparison. The textbook approach is a search cluster: stand up Elasticsearch, index everything, and query for candidates. Geocode-first replaces that infrastructure with a single pass through the data. Two records in the same ~5 km cell are candidates, and every other pair is skipped. The geocoder has already done the partitioning. We measured the matcher resolving half a million records in about a minute in one Node process on commodity hardware. The baseline requires a search index, while this approach needs no server, Docker, or long-running process. The architecture matters more than the exact timing.
Distance becomes a feature you can calibrate. Records for the same building are typically ~30 meters apart, and records on the same block ~300 meters. The geocoder knows its own error. Rooftop points are tight, interpolated points are looser, and centroids are looser still, so distance evidence can be weighted by placement quality. A string matcher has no equivalent. It can report that two street names are spelled similarly, but it cannot tell whether they refer to the same building.
A shared address is weighted by how rare it is. Two records agreeing on the address of a clinic tower is weak evidence that they are the same entity, because fifty providers share that building. Two records agreeing on a rural address with one occupant is strong evidence. This is TF-IDF for places: an address agreement is weighted by the count of distinct entities sharing that address. On a real provider-registry deduplication, enabling this weighting raised F1 by roughly twenty points in a single change. Most of the F1 increase came from recall, because a provider's rare address rejoined records that name variations had split apart. We had expected precision to supply most of the increase, and we adjusted our understanding to the data.
The receipts
We ran this on real public data: the national provider registry (NPPES), the FCC's Rural Health Care funding filings, and a state nursing-facility registry. The three datasets share no key, and each is published in the fragmented form that compliance data typically has.
Within the provider registry, we used the registry's own entity ID as held-out ground truth. The resulting score was low, and a later section explains why that score was misleading. We also recorded which changes fixed real errors and which made results worse, including the negative results.
Across the three datasets, the matcher links records without a shared ID, using only geocoded location plus name agreement. It links rural Texas hospitals across the funding program and the provider registry: Hunt Memorial Hospital District, Uvalde County Hospital Authority, and Winkler County Memorial Hospital. Each hospital has a registration record in one dataset and a funding record in another. The matcher joins them because they are at the same building. That join requires geocoding first.
Once the records are joined, you can ask which entities appear in the eligibility sources but not in the funding sources. Today someone finds that anti-join by inspecting a map by hand. We produce it as a layer that loads directly onto the map.
That result needs careful interpretation. We produce the reconciliation, and the analyst draws the conclusion. An entity in the "eligible rather than enrolled" set is a candidate for review and does not imply wrongdoing. A gap can mean the entity did not apply, applied under a name we did not resolve, is not eligible, or has some other ordinary explanation. The tool resolves public records into an analyzable shape and surfaces candidates. The analyst decides what a correlation means.
The ground truth changed the score
To measure deduplication within the registry we needed ground truth. The registry provides a stable, government-issued ID on every provider. A cluster score against that ID appears objective.
That ground truth is wrong, and it makes the matcher look worse than it is. The ID is a registration number, and one organization can hold several. One hospital system holds a separate registration for every billing subpart. Baylor College of Medicine appears four times at a single address. When the matcher correctly merges those four records into one entity, the registration-number ground truth scores those pairs as over-merges. A better matcher therefore gets a lower score.
We graded the identical cluster output, from the same model, against a ground truth that collapses same-organization records at the same building. F1 rose without any code change:

We froze the hardest cases (co-located records with near-identical names that the registration ID separates) and adjudicated them one at a time: 120 of 120 were the same real-world organization. None were two unrelated organizations merged by mistake. The class we had logged as our largest source of error was almost entirely the matcher being correct and the ground truth being too literal.
We trusted the first number and spent time building corroboration features to reduce apparent over-merging. Those features left precision unchanged because the over-merging did not exist.
A matching F1 is uninterpretable unless it states its truth grain. Report the ground truth next to the number every time. When the number is low, check the ground truth before blaming the model.
At 68.1%, F1 is still mediocre. The ground-truth analysis explains part of the low number, but it does not make the number good. The matcher still misclusters. Rural route addresses and PO boxes defeat the geocoder: a shared box at a post office resolves to the same rooftop coordinate for every resident, so the distance feature provides no information. Rooftop interpolation can place a strip-mall suite on the wrong unit. The performance table includes those rows, and we are working on them.
Why a single Node process matters
A geocoder and a record-linkage library could provide some of this. The integration comes from using the same calibrated geocoder for blocking and distance weights, all in one process without an external service.
That integration is an architectural property. Geo-blocking is what lets candidate generation run in-process. A string matcher needs a search cluster because it cannot partition the problem cheaply, and geocode-first removes that need. The whole pipeline (parse, geocode, block, score, and cluster) installs with npm install and runs as a function call, without Elasticsearch, Docker, or a long-running server. For a compliance team with a folder of CSVs and no infrastructure budget, that makes the work an afternoon's task instead of a project.
The approach is to match on location instead of spelling and let the coordinates determine the candidates.